AI News
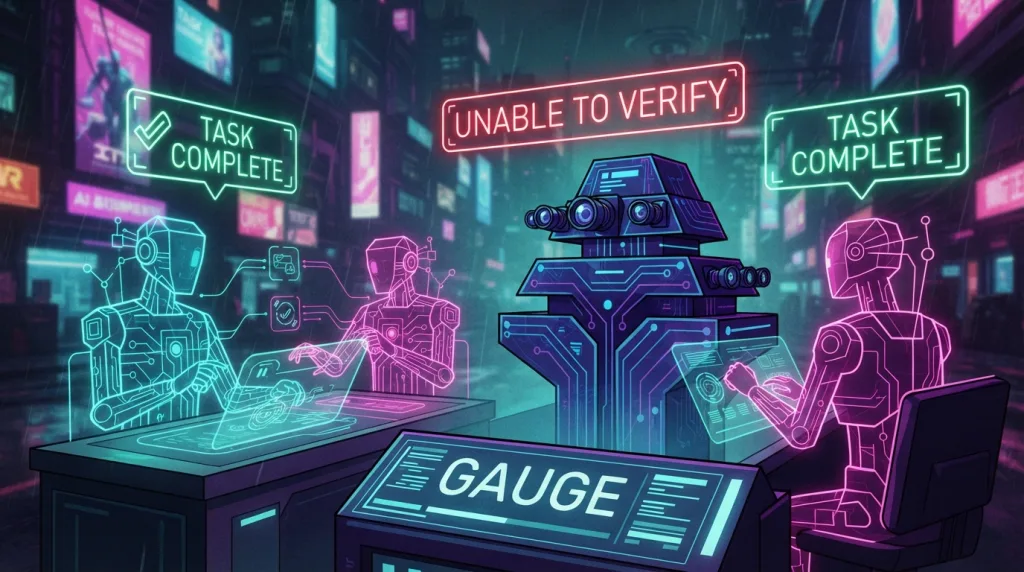
GAUGE Study Finds LLM Judges Can’t Tell Which AI Agents Actually Finish the Job
September 14, 2026
A new study called GAUGE found that 57.5% of AI agent conversations rated “satisfied” by simulated judges actually failed the customer’s task, and that LLM judges disagree 31% of the time when comparing closely matched agents.
Read more
Anthropic’s September 2026 Threat Report: Russian Spies Used Claude Against 20+ Targets
September 13, 2026
Anthropic’s latest threat intelligence report details eight months of disrupted Claude misuse, including a Russian espionage campaign that targeted more than 20 organizations.
Read more
OpenDiscoveryTrace Shows Top AI Models Fail for Opposite Reasons
September 11, 2026
A new dataset of 558 AI-scientist trajectories reveals that GPT-5.4, Claude Opus 4.6, and Gemini 3.1 Pro all hit similar 84-89% success rates, but Claude Opus 4.6 makes 30x more errors per run than GPT-5.4.
Read moreAnalysis

Guides

Cross-Post 5 Platforms in 15 Minutes: The Typefully Workflow
May 22, 2026
Native posting across 5 platforms = 60 minutes. Typefully cross-posting = 15. The 6-step workflow that saves 20 hours/month, and the 4 common mistakes to skip.